Cloud infrastructure
Crawl.io
Distributed crawling. Reproducible infrastructure.
- Distributed web crawling for LLM training, RAG, and search datasets.
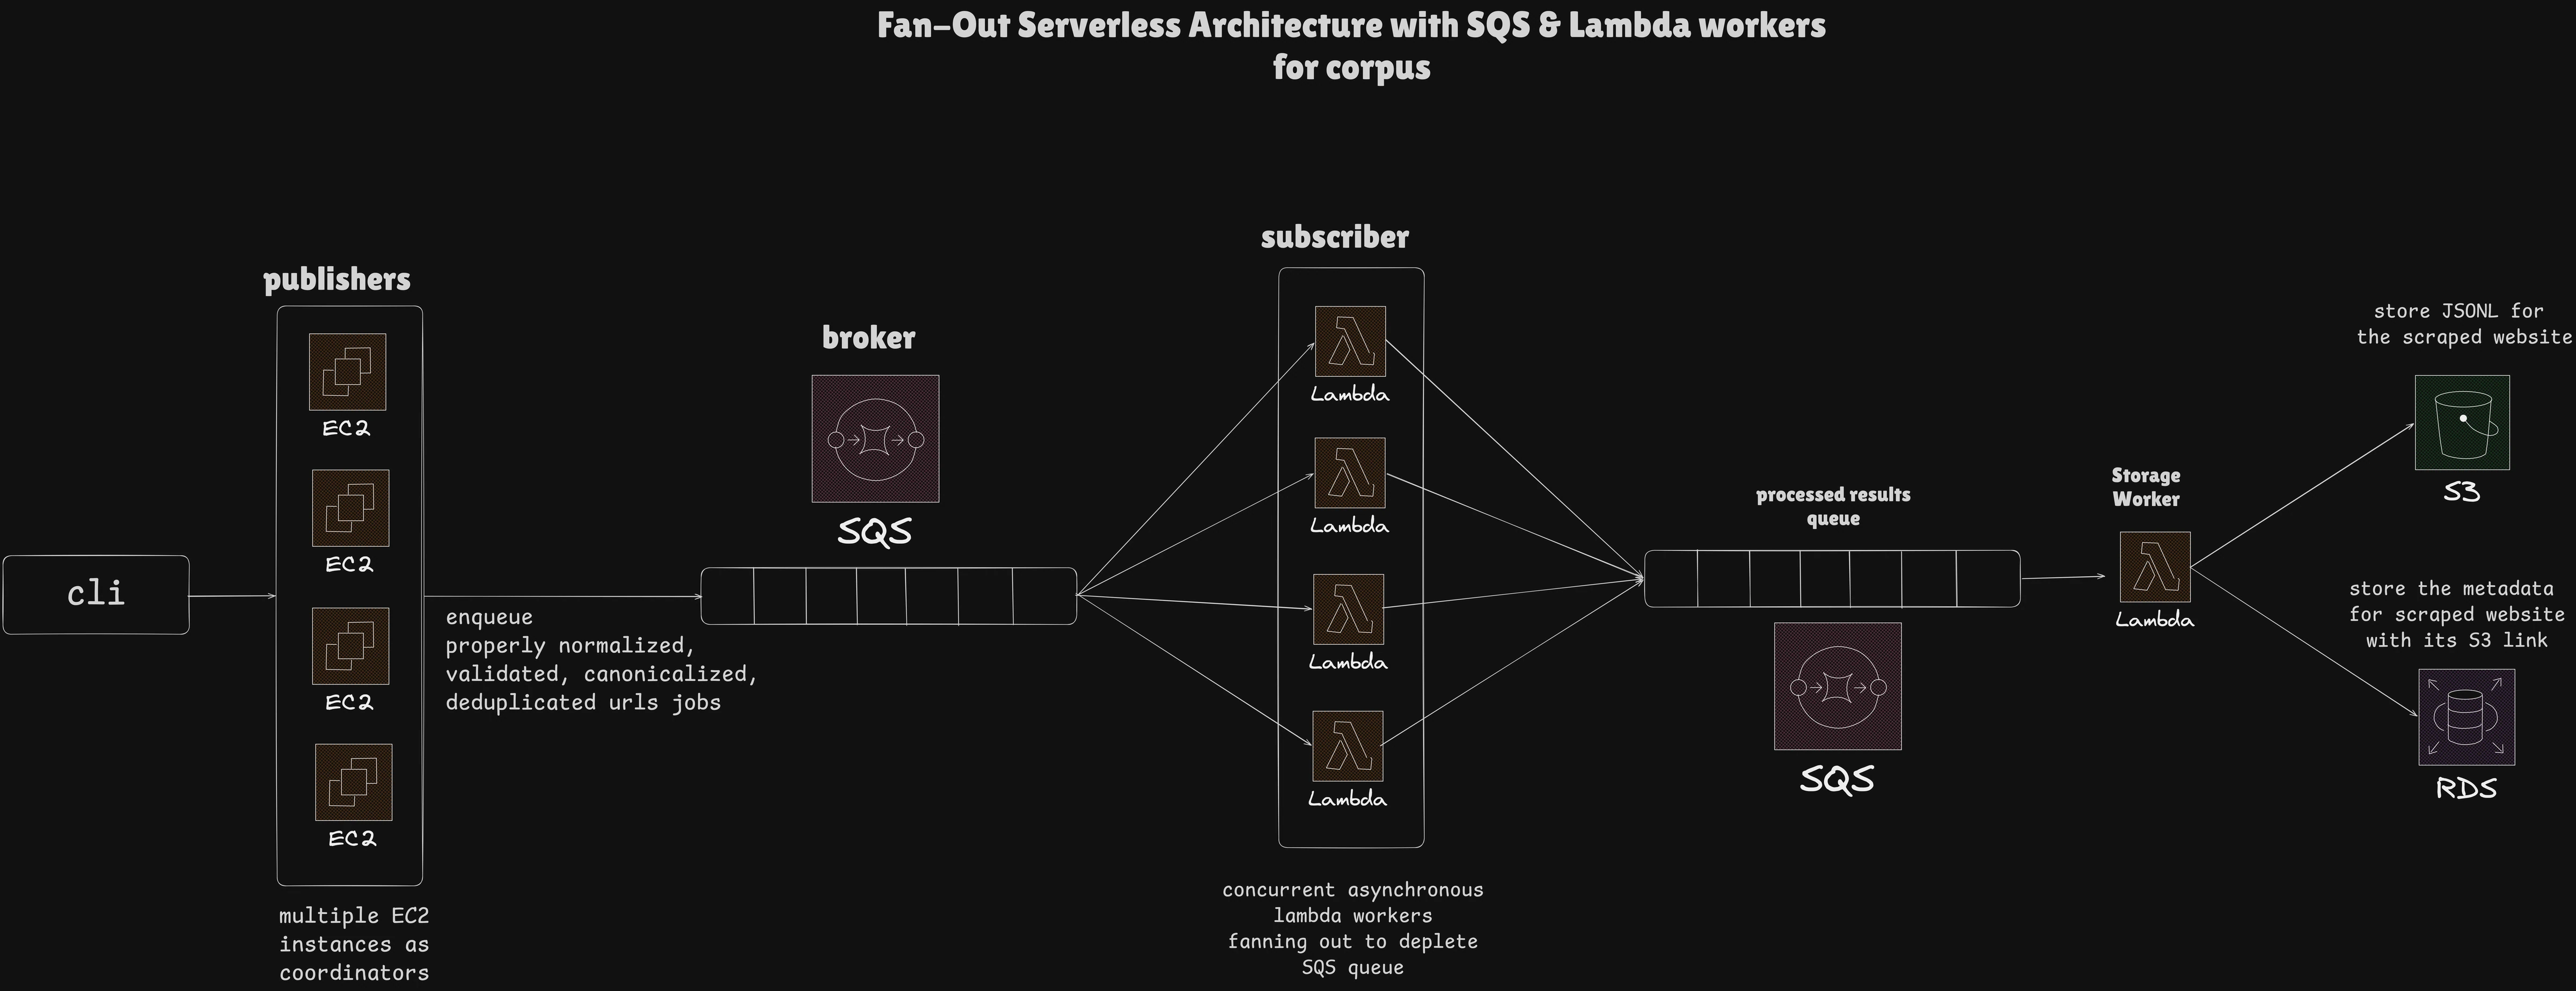
- Decoupled AWS services for scheduling, crawling, URL discovery, and storage.
- Reproducible deployments through Terraform.
- URL deduplication, crawl limits, filtering, and robots.txt compliance.
Decoupled by design
- Separate scheduling, crawling, discovery, and storage across AWS services.
- Provision infrastructure with Terraform.
From a URL to a dataset
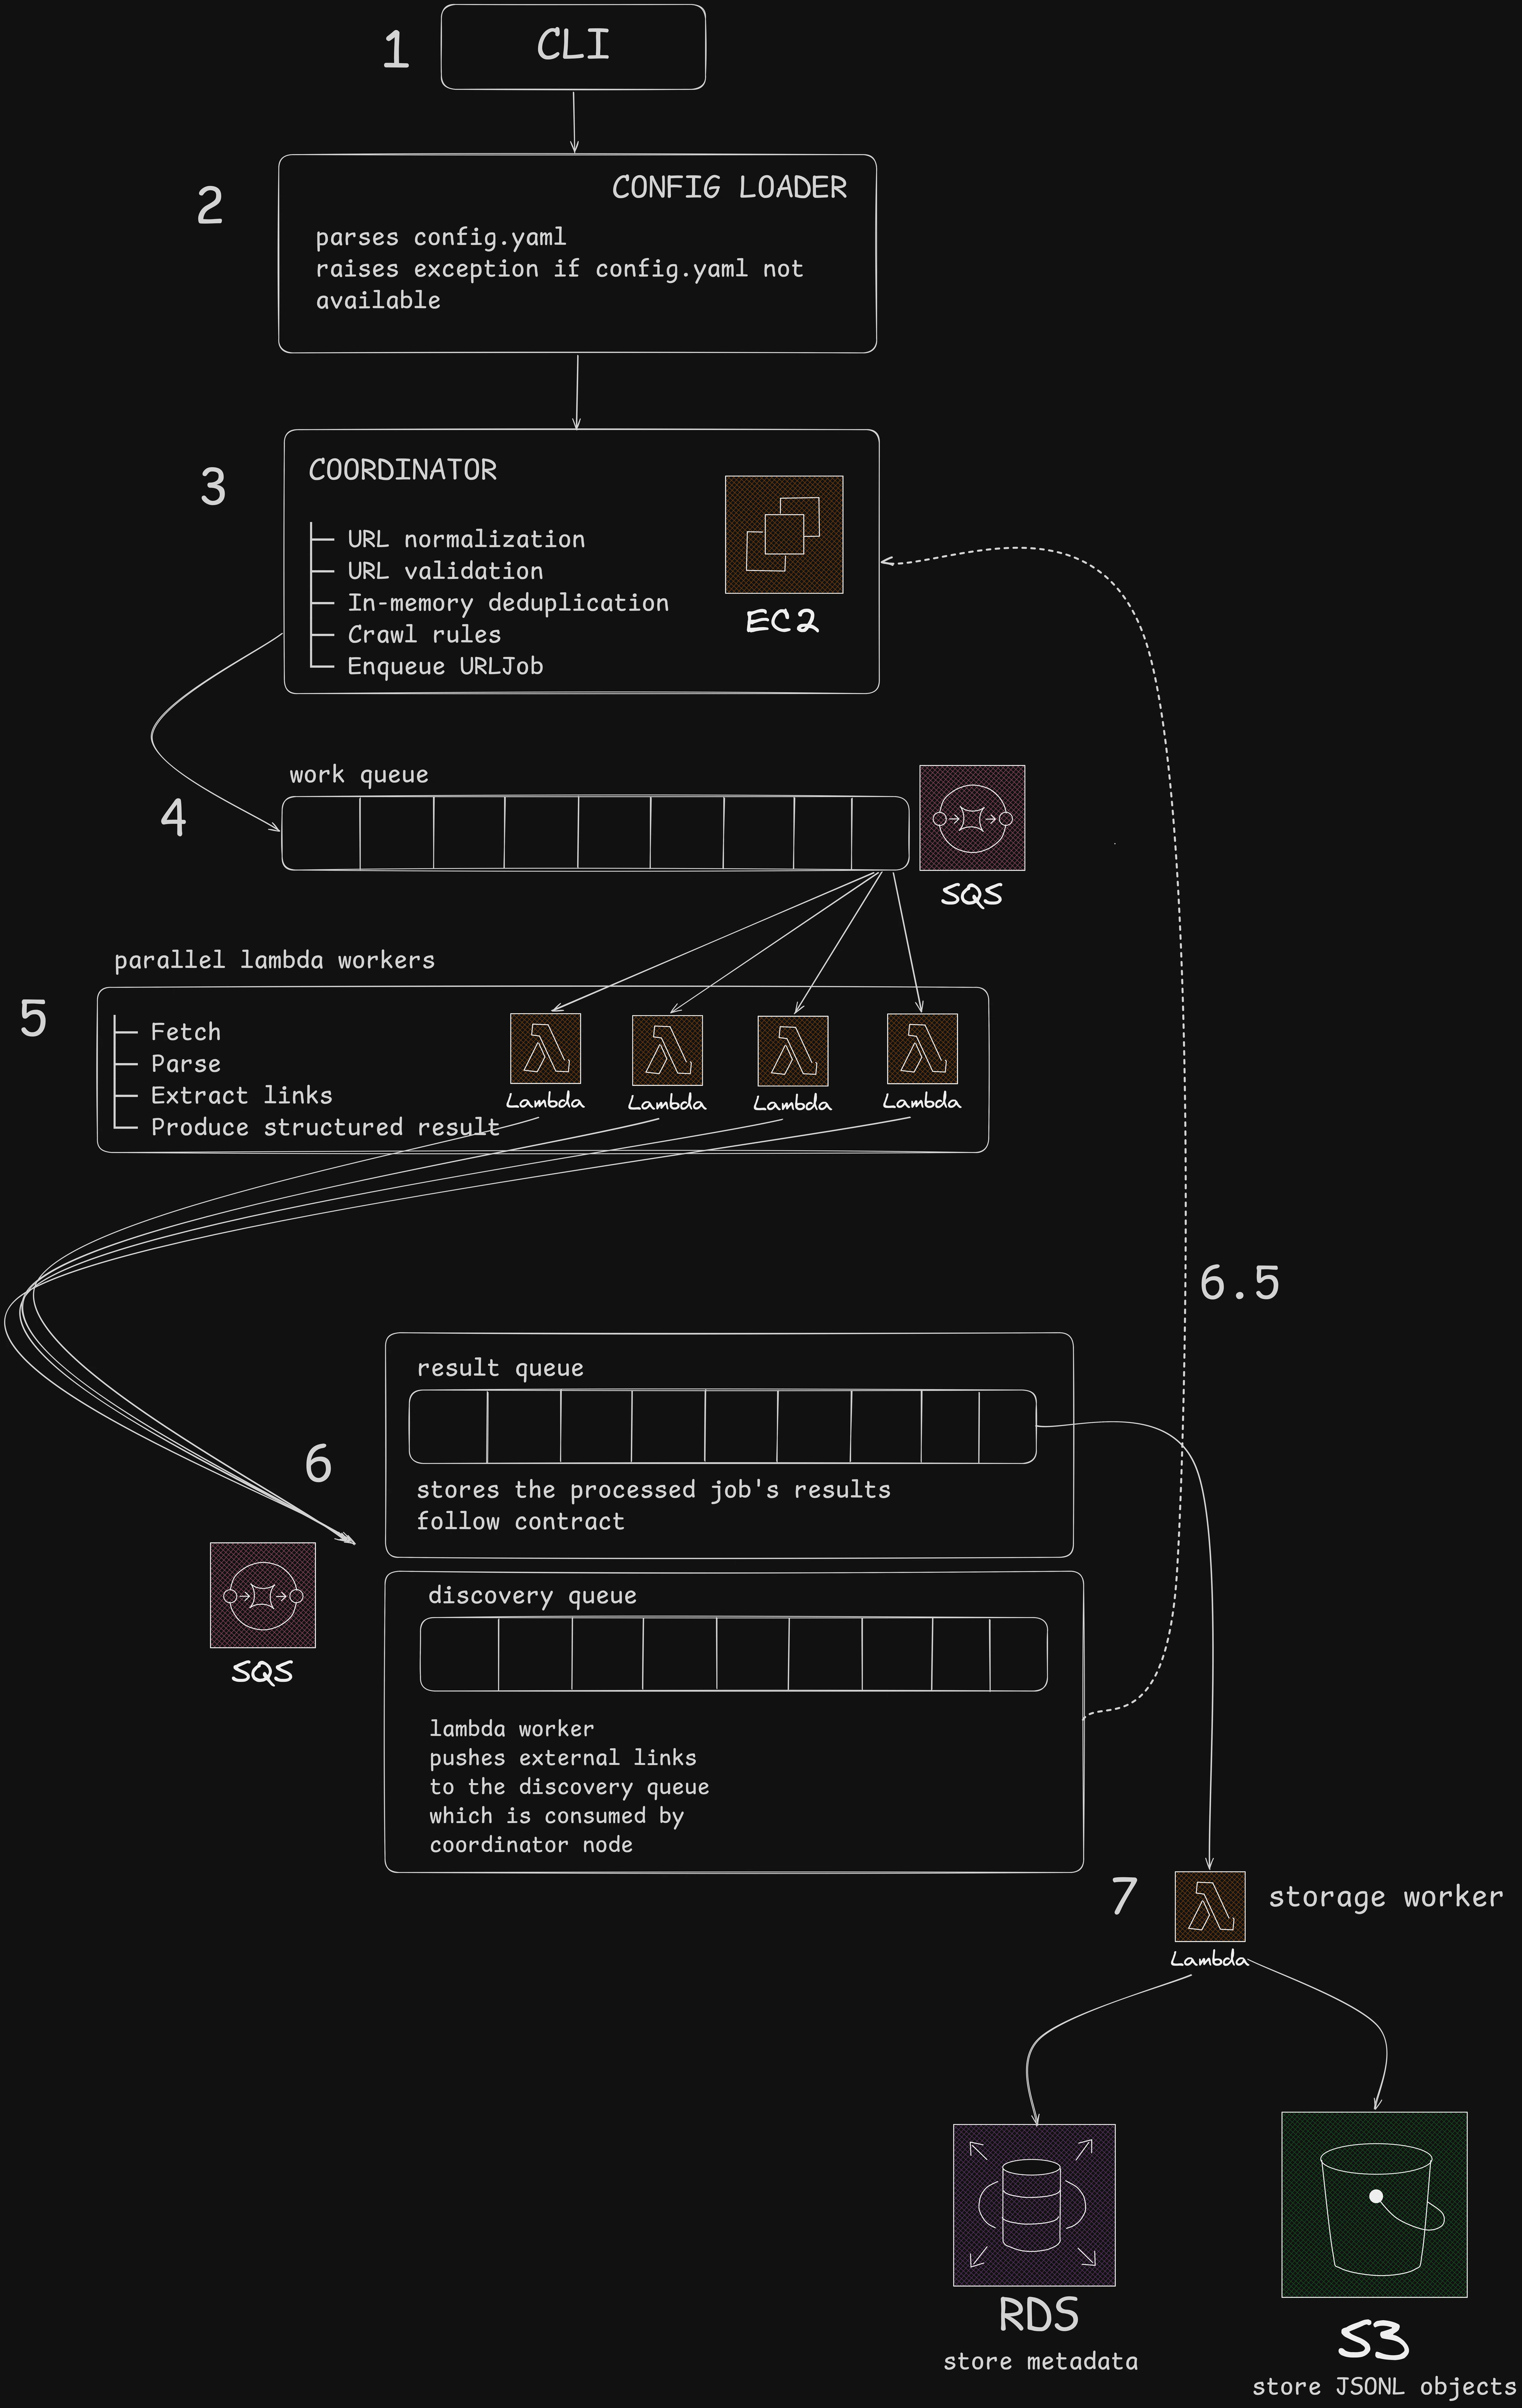
- Load crawl configuration and normalize, validate, and deduplicate URLs in the coordinator.
- Fetch pages, parse content, and extract links in parallel Lambda workers.
- Send discovered links back to the coordinator and processed results to a separate storage worker.
Observable and testable
- Use structured logging and backend-independent metrics.
- Keep deterministic pytest tests and deployment troubleshooting documentation.
Built with
- Python
- httpx
- BeautifulSoup4
- Protego
- Pydantic
- SQLAlchemy
- AWS EC2 / Lambda / SQS / S3 / RDS
- Terraform
- pytest